Internet Archive New Uploads Screensaver
The Internet Archive New Uploads screensaver streams real items just added to archive.org across every format. It is free, runs in your browser, and ESC exits.
Live preview
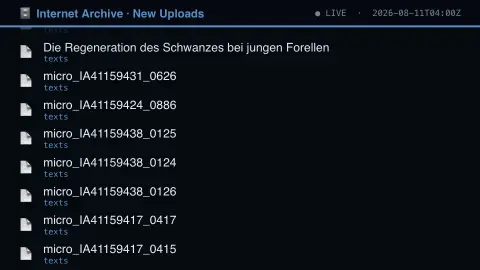
Press ESC to leave fullscreen. Settings are saved in your browser only.
How the Internet Archive New Uploads screensaver works
The saver reads real recently-added items from the Internet Archive's own advanced search API.
Each entry shows a real title and media type, sorted by real upload time.
The pipeline refreshes the feed regularly as new items are added.
No key is required for this key-less public endpoint.
A glimpse of the Internet Archive's intake
The Internet Archive is a non-profit digital library based in San Francisco. Best known for the Wayback Machine, which preserves snapshots of web pages, it also hosts large collections of books, audio, video, software and images. Content is stored in items, each with a unique identifier that appears in its address as archive.org/details/ followed by the identifier. Identifiers must be unique across the whole Archive and cannot be changed once set, which is why many names look like slugs and not titles.
Every item has a mediatype describing its main content. The accepted values include texts, etree, audio, movies, software, image, data, web and collection, and this display uses them to tell the intake apart. A run of similar names often reflects a single batch from one uploader or partner rather than separate contributors.
A new item is not a verified or curated one. Uploads can be of uncertain provenance and rights status. The added date records when an item was added to the Archive’s public search index, which may differ from the date of the original work, sometimes by decades.
A worked example
A real newly-uploaded software title or recording scrolls past exactly as it landed on archive.org moments earlier.
Settings & tips
- Coverage spans real video, audio, software and text uploads, not just books.
- Accent recolours the ticker text.
- The Internet Archive is a real nonprofit digital library.
Frequently asked questions
- Is this real archive data?
- Yes — real newly-added items from archive.org's own API.
- Is a key needed?
- No. The advanced search API is fully key-less.
- Does this include books only?
- No — it covers real video, audio, software and text uploads.
- Is it free?
- Yes — free, no download, in your browser.
- Why do identifiers look like codes or slugs?
- Each Archive item gets a unique identifier that forms part of its web address, and it cannot be changed after it is set, so uploaders and tools often choose compact, hyphenated names.
- What are the media types?
- Categories the Archive assigns to each item, such as texts, audio, movies, image, software, data and web.
- Are these items vetted before they appear?
- Being listed here does not mean an item has been reviewed or curated. Treat new uploads as unverified.