arXiv Paper Firehose Screensaver
The arXiv Paper Firehose screensaver scrolls new research papers as they're posted to arXiv, the open preprint server — real papers, key-less, gathered by a background pipeline (arXiv's API doesn't allow direct browser access). It's free, runs in your browser, and ESC exits.
Live preview
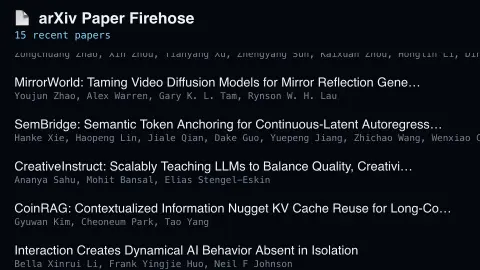
Press ESC to leave fullscreen. Settings are saved in your browser only.
How the arXiv Paper Firehose screensaver works
A background pipeline queries arXiv's public API for the most recently submitted papers in your chosen field, with no key required.
Each paper scrolls through with its real title and author list.
Pick computer science, physics, math or quantitative biology, or leave it on the default.
Readings refresh on the pipeline's schedule, not live tick by tick.
Preprints and how arXiv organises them
arXiv is an open repository for scientific manuscripts, founded by Paul Ginsparg in 1991. It covers physics, mathematics, computer science, quantitative biology, quantitative finance, statistics, electrical engineering and systems science, and economics. Authors post their work there so that it is available to everyone once it has been moderated, instead of waiting for a journal.
Each paper has an identifier of the form YYMM.number, where the first digits give the year and month of submission and the number is a sequence that has had five digits since 2015. A version suffix such as v2 marks revisions, and the bare identifier points to the latest version. The identifier carries no subject information, so a paper can be reclassified after it is announced.
arXiv uses moderation, not peer review. Moderators check whether a submission fits the subject area and has scholarly value, and arXiv states that material is not peer-reviewed by it. Hosting a paper does not mean arXiv endorses its methods or conclusions. Many arXiv papers are later published in journals or conferences, and some are not. Titles show what researchers are posting, but reading one is no guarantee of the paper’s quality.
A worked example
Set it to Computer Science and real papers scroll past on everything from machine learning to distributed systems — the actual arXiv submission stream, snapshotted by the pipeline.
Settings & tips
- Field switches which arXiv category feeds the scroll.
- Accent recolours the paper titles.
- Run
automation/run.py arxivfeedon your pipeline machine to refresh the data.
Frequently asked questions
- Is this real research?
- Yes — arXiv is the real preprint server used daily by researchers worldwide; these are genuine submissions.
- Why does it need a pipeline?
- arXiv's API doesn't allow direct browser requests (no CORS), so a small background script fetches it and saves a snapshot the saver loads — no key needed, just a server-side fetch.
- Has it been peer-reviewed?
- Not necessarily — arXiv hosts preprints, shared before or during peer review.
- Is it free?
- Yes — free, no download, in your browser.
- How is an arXiv identifier structured?
- Since April 2007 identifiers take the form YYMM.number, combining the year and month with a zero-padded sequence number, which has had five digits since January 2015. The identifier reveals roughly when the first version was posted.
- Can a paper be changed after posting?
- Yes. Authors can submit new versions, and previous versions remain accessible. A withdrawal creates a new version marked as withdrawn rather than erasing the earlier ones.
- Does arXiv peer-review papers?
- No. Submissions are moderated for subject fit and scholarly value, but arXiv states that material is not peer-reviewed by it.